GPT-6 Astra Scored 99.9% and 62.7% on the Same Benchmark.
OpenAI shipped GPT-6 Astra claiming the AGI era. Its two ARC-AGI-3 scores differ by 37 points, and the gap came entirely from the harness.
OpenAI shipped GPT-6 Astra on September 3 with a one-line pitch: "Anything you can do on a computer, Astra can do for you. Fast."
Greg Brockman, president and co-founder of OpenAI, went further. "I think it's not unreasonable to feel that we are now in the AGI era." Tobi Lutke replied to the benchmark chart with a single word: "Singularity."
Then the numbers arrived, and the most important one is not on OpenAI's chart. On ARC-AGI-3, Astra scored 99.9%. It also scored 62.7%. Same model, same benchmark, same day. What changed was the harness it ran inside. The 99.9% is the best Provider Adapter run, at high reasoning effort; the 62.7% is the best Standard run, at maximum. Hold both at maximum and the gap barely narrows: 62.7% neutral, 98.6% on OpenAI's own rig, for $8,766 less.
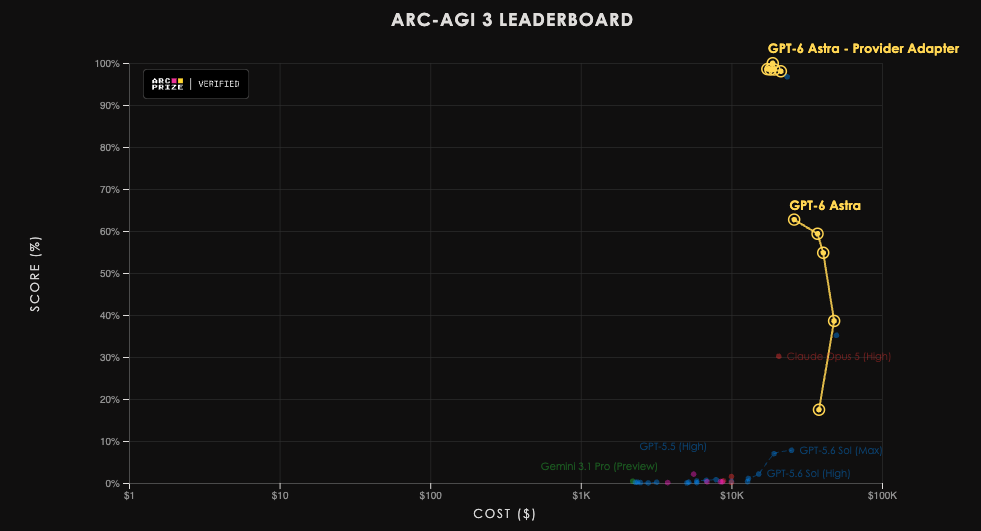
ARC-AGI-3 Semi-Private, score against total cost. Both axes are log scale.
What the two harnesses actually differ on
ARC Prize runs a standard harness on purpose: a provider-neutral interface so numbers can be compared across labs. Under it, a model carries forward only the notes it explicitly chooses to keep. Everything it is thinking is visible and portable.
OpenAI's Provider Adapter does something different. It preserves opaque reasoning state between requests and uses compaction to manage long conversations, so the model reuses prior work rather than reconstructing it. That is a legitimate product capability, shipped in the Responses API, and it is genuinely useful. It is also not what the other models in the comparison chart were given.
ARC Prize was careful about the conclusion, and the caution belongs next to the number.
Kamradt
"While we believe Astra represents meaningful progress towards generalization, we are not claiming that it is AGI."
The index that did not move
Here is the other number worth holding. On Artificial Analysis's Intelligence Index, Astra scores 61. GPT-5.6 Sol, the model it replaces, also scores 61. Claude Fable 5.1 scores 66.
So an independent aggregate shows no gain at all, on the same day OpenAI published a sweep of state-of-the-art claims. That looks like a contradiction and it is not one. Read the two together and a coherent picture appears:
Astra is a large jump in doing and roughly flat in thinking. The benchmarks it wins measure long-horizon agentic execution: computer use, terminal work, persistence across hours. The index it does not move measures general reasoning quality. Both can be true, and the consequence for you is that this is not a blanket upgrade. It is a task-shaped one.
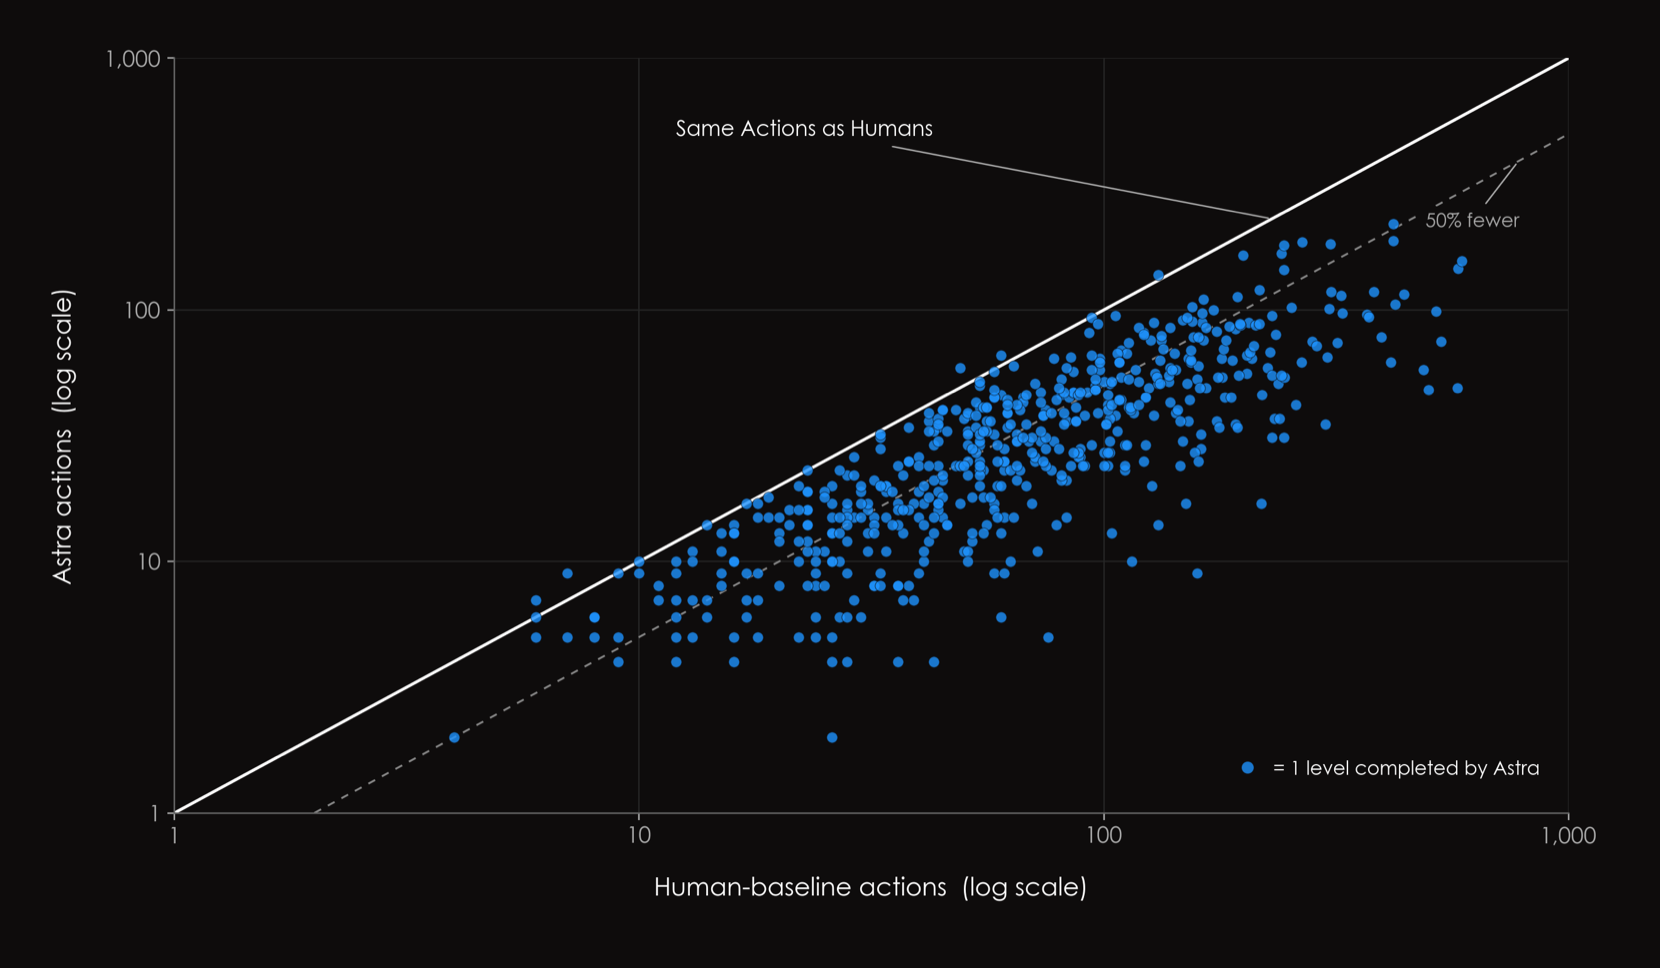
Astra used fewer actions than the median tested human on 96% of levels. This is the "doing" half of the picture, measured.
What people who actually used it said
The early-access reads were unusually consistent: enormous at operating software, less special at judgment.
Shipper
"It's a big upgrade from 5.6-Sol, with some frustrating habits that keep it from matching Fable at the top end."
Shipper calls it the best writing model he has used, with very little slop and easy steering, and says computer use is "wild, it can go for hours at a time using complicated apps to get work done." Against it: it overcomplicates, and Anthropic's Fable still has better instincts for building a product. The tell is buried in the piece itself. Astra wrote the vibe check's first draft from a single prompt, and Shipper initially mistook it for a colleague's work.
Levie
"It is now the best model we've ever tested on our expanded and hardest test set."
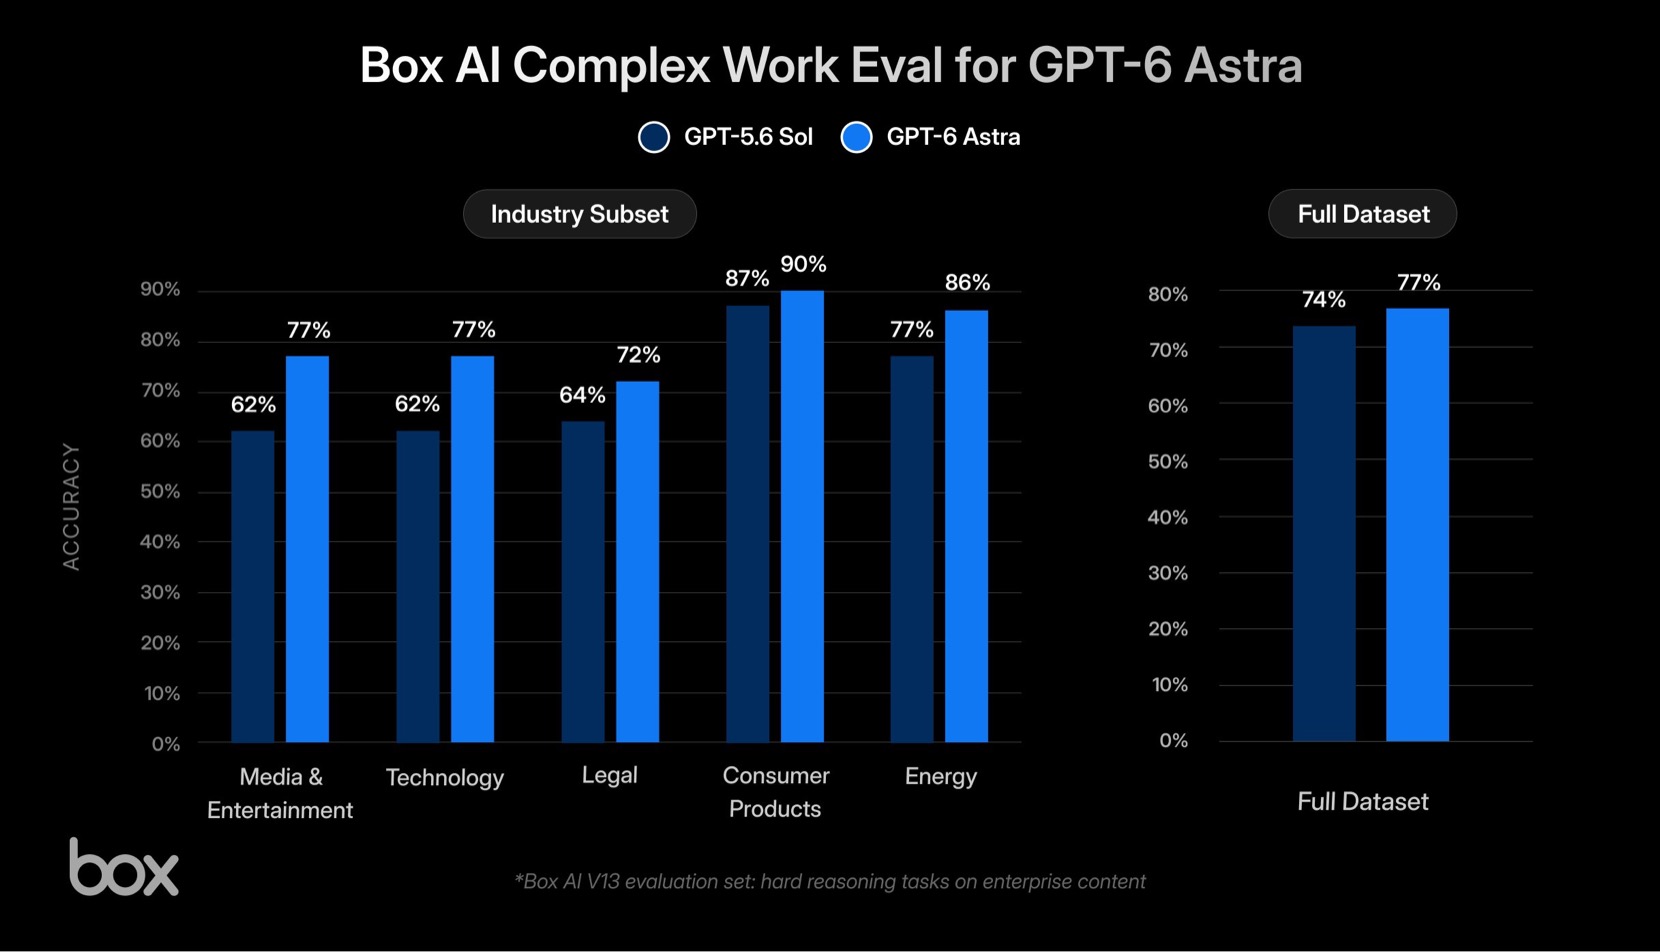
Worth holding both numbers. The per-industry jumps are large, and the full-dataset gain is 74% to 77%.
Claire Vo, who builds ChatPRD, produced the most concrete build log: one-shot coding wins that Fable and 5.6 could not match, an AIM-style Mac desktop app in a single attempt, a hardware CLI she had chased since GPT-5.5, and a ChatPRD feature she had "thrown every model at for six months" finally landing at 90%.
Ethan Mollick pointed it at tens of thousands of his own emails, writings and calendar entries and had it assemble a personal knowledge base of research, contacts, ideas, relationships and tasks. That is the clearest published example of the long-horizon mode, and it is the one most likely to matter inside a company.
The counter-take of the day
Against Brockman's AGI framing, the sharpest reply came from someone describing his own setup rather than the model.
"All of my personal assistants are now reading each other's updates, and summarizing what the others learned. This feels way more like agi than astra."
That is the same lesson the ARC-AGI asterisk teaches, arrived at from the opposite direction. In both cases the thing producing the capability is the system around the model, not the weights. A 37-point swing from a harness change and a set of agents summarising each other are two versions of one finding.
What it costs, and what it does not tell you
$10 per million input tokens, $50 per million output. That is 2.5x GPT-5.6 Sol, and it is exactly level with Claude Fable. Note the second comparison, because it is the one that matters for routing: at identical prices, Fable currently sits five points higher on the independent reasoning index, and Astra is far ahead on computer use.
Two billing details that are not in the headline rate. Search and computer-use tool calls bill per call on top of tokens. And rollout started through a limited Daybreak Access programme before ChatGPT tiers, the API and AWS, which Daring Fireball called a soft release and Forbes called a curious false start.
On safety, both frontier labs have now shipped a model with a cyber gate attached. Astra supports defensive work, secure code review and patching, and refuses advanced offensive work such as writing proof-of-concept exploits.
The one thing to take from day one
Not "AGI is here" and not "the benchmarks are fake." Both readings skip the finding.
The most valuable number OpenAI published this week is the gap between 62.7% and 98.6% at identical reasoning effort, because that gap was produced entirely by scaffolding: reasoning state carried between calls, and compaction across a long context. At matched maximum effort it made the model 36 points better and 34% cheaper, and across every effort level it ran 3.66x faster on 49% fewer tokens.
If a harness change is worth 36 points to a frontier lab on a benchmark, it is worth more than that to you on your own workflows, where nobody has tuned anything yet. The scaffolding is the product, and it is the part you own.
Buy the harness, not the headline.

Founder of nativefirst.ai. Runs everything on agents and writes down what works.